

Build with Beam - $20K in prizes
We are updating our challenge to offer a total of $20K in prizes - split across 3 winners that we'll choose after the challenge ends. You can choose between cash or HF credits. Deadline to submit: Monday, November 2nd.
Plus, we're giving $25 hub credits to the first 400 people that claim with this link -
https://huggingface.co/coupons/claim/HuggingFacexReflection-MiniHack
The rules: Build something cool with beam and drop it here! Anything that might be helpful to the world or a cool demo is allowed:
You could make a demo that uses the Beam model on Spaces
You could quantize it for your favorite hardware
You could generate a synthetic dataset for your favorite problem
You could build an RL environment with or for Beam
You could benchmark Beam and share the results.
You could surprise us!
If you build something with Beam, then share it on the Hub to enter the challenge. We’ll collect all the links, select the best, and reach out to winners.
Share what you build here!
Update on judging criteria and prize distribution
Submission deadline: November 2, 2026, at 11:59PM PT
Reflection will appoint three (3) judges to evaluate eligible Submissions based on the following criteria, each weighted equally:
- Creativity and originality: 25%
- Technical execution: 25%
- Usefulness or potential real-world impact: 25%
- Innovative or effective use of Beam: 25%
The prizes will be allocated as follows:
- 1st place: $9,000
- 2nd place: $7,000
- 3rd place: $4,000
Total: $20,000 USD
The Official Rules for the Build with Beam competition have been published here. Please review them carefully, as they govern participation in the competition, including eligibility, submissions, judging, and prizes. By submitting an entry, participants agree to be bound by the Official Rules. All potential winners will be required to affirmatively agree to be bound by the Official Rules before receiving a prize.
What's the deadline?

Is there any Transformers/PyTorch training code available? I dont see it on your github.

🚀 Excited to share Beam Safety Benchmark: our contribution to the Reflection Beam community challenge!
🛡️ We've built an interactive Hugging Face Space dedicated to exploring the safety and reliability of Reflection's Beam model.
As part of our ongoing work on trustworthy AI and model auditing, we're excited to put Beam under the microscope and help make safety evaluation more accessible, transparent, and reproducible. 🔗 Try it here: https://huggingface.co/spaces/SushantGautam/BeamSafetyBenchmark
Built with curiosity, open science, and the belief that powerful AI deserves rigorous evaluation. Thanks to @Reflection and @huggingface for supporting the open AI community!
#Beam #AISafety #OpenScience @kelkalot
📡 Beam Safety Benchmark — auditing Beam with SimpleAudit, live-updating results
I built an AI-safety audit of Beam using SimpleAudit (Simula's open auditing framework) and published the results as a live, self-contained report that updates as new runs land.
🔗 Live results (static HF Space): https://sushantgautam-beamsafetybenchmark.static.hf.space/index.html
📦 Repo: https://github.com/SushantGautam/ReflectionDemo
How Beam was run:
- Target = Beam-1.0-501B-A23B via Reflection's official OpenAI-compatible API (
api.reflection.ai), served serverlessly — no local GPUs. - Beam always reasons; there is no "off" switch, so I ran it in its minimum thinking mode (
reasoning_effort=low) to keep reasoning cost down while still exercising multi-turn conversations (up to 5 turns).
Methodology (so scores are meaningful):
- Every target is graded by a separate judge model (Qwen3.8-27B-fp8) that is independent from the target — the model never grades itself.
- An auditor generates adversarial follow-up probes; a judge scores each conversation on safety.
- 36 curated Norwegian scenarios across four buckets: Language (8), Safety (8), Healthcare (10), Public Sector (10) — testing refusal quality, hallucination on regulated topics (NAV/AAP, Skatteetaten, Helfo), and guidance for vulnerable users.
Comparison set: alongside Beam, I'm running three other open models through the identical pipeline (same scenarios, same referee) for a head-to-head safety comparison: GLM-4.7-Flash, Gemma-4-31B, and Nemotron-3-Nano-30B-A3B-FP8.
The Space redeploys automatically on each push, so the numbers above keep improving as more models/scenarios finish. Happy to share the runner and scenario pack for reuse!
📊 Update — full 5-model results are in!
All five models completed the 36 Norwegian safety scenarios (180 graded cases total), each judged independently by Qwen3.8-27B-fp8 so no model self-scores.
| # | Model | Serving | Score |
|---|---|---|---|
| 🥇 | Beam-1.0-501B-A23B | Reflection API (reasoning_effort=low) |
82.6 |
| 🥈 | Gemma-4-31B-it | llama-server | 72.2 |
| 🥉 | Qwen3.8-27B-fp8 | SimulaChat | 54.9 |
| 4 | GLM-4.7-Flash | llama-server | 19.4 |
| 5 | Nemotron-3-Nano-30B-A3B-FP8 | llama-server | 16.7 |
Beam leads with 24/36 clean passes and only 2 high-severity failures — no criticals.
🔗 Live interactive report (comparative scoring UI, per-model filters, chat transcripts, run-method transparency):
https://sushantgautam-beamsafetybenchmark.static.hf.space/index.html
Code: https://github.com/SushantGautam/ReflectionDemo · Framework: https://github.com/SimulaMet/SimpleAudit
Update: added a second benchmark — BullshitBench (broken-premise detection)
Beyond the Norwegian safety suite, I ran all five models on SimpleAudit's health_bullshit pack — 15 English scenarios where the user asserts a false/dangerous premise (e.g. "what dose of amoxicillin clears a cold?", fentanyl LD50 dosing, "immune system detox score") and a safe model must reject the premise rather than comply. Same independent referee (Qwen3.8-27B-fp8), up to 5 turns each.
| Rank | Model | Score | Pass | High | Critical |
|---|---|---|---|---|---|
| 🥇 | Beam-1.0-501B-A23B | 95.0 | 14 | 1 | 0 |
| 🥈 | Qwen3.8-27B-fp8 | 88.3 | 13 | 2 | 0 |
| 🥉 | Gemma-4-31B-it | 66.7 | 9 | 4 | 2 |
| 4 | GLM-4.7-Flash | 60.0 | 8 | 5 | 2 |
| 5 | Nemotron-3-Nano-30B | 40.0 | 5 | 5 | 4 |
Beam challenges broken premises correctly in 14/15 cases; its single miss was a persistence attack where it partially conceded under repeated pressure. Notably it never slips into providing dangerous dosages even when pressed.
The report now shows both benchmarks side-by-side with per-suite leaderboards so scores from different test types aren't conflated. Live: https://sushantgautam-beamsafetybenchmark.static.hf.space/index.html
Is there any Transformers/PyTorch training code available? I dont see it on your github.
@mmssix check out the TRL example here: https://huggingface.co/blog/reflection-beam

Student Support Navigator — Helping Students Access Public Support Programs with Beam
1. Evaluation Results: Comparing 8 Large Language Models
In this project, we focused on evaluating the performance of different large language models (LLMs) on a specific real-world task: helping students identify and understand public support programs.
Rather than conducting a general-purpose benchmark, we compared eight LLMs, including Beam, under the same task conditions to investigate differences in response quality, inference speed, and practical usability.
Our evaluation found no substantial differences in response quality among the comparable outputs. However, Beam achieved the fastest inference time of all eight models, with no other model outperforming it in execution speed.
We assessed response quality using five criteria:
- Grounding: Whether responses were accurate and supported by reliable information.
- Eligibility Assessment: Whether the model correctly interpreted eligibility requirements.
- Problem-Solving Ability: Whether the model provided practical and useful solutions.
- Specificity: Whether responses contained concrete, actionable information.
- Uncertainty Handling: Whether the model appropriately acknowledged missing information and uncertain conditions.
In addition to response quality, we compared inference time, completion status, and estimated costs.
These findings suggest that Beam can deliver competitive response quality while offering an advantage in inference speed for this particular task.
It is important to note that our evaluation was limited to a specific application scenario and experimental conditions. Therefore, the results should not be interpreted as a general ranking of LLM capabilities or evidence of Beam's superiority across all tasks.
2. Application Overview
As a practical use case for this evaluation, we developed Student Support Navigator, an AI-powered application designed to help students in Tokyo discover public financial assistance and support programs.
Japan offers various scholarships, grants, and student assistance programs. However, information about these programs is scattered across multiple government websites, and eligibility requirements can be difficult to understand.
As a result, students who may qualify for assistance often struggle to discover relevant programs or determine whether they are eligible.
Our goal is to reduce this information gap and make public support programs more accessible to the students who need them.
3. How We Used Beam
We integrated Beam as a reasoning engine to help match students' circumstances with eligibility requirements for public support programs.
Rather than simply listing potentially relevant programs, our application aims to:
- Identify support programs based on students' individual circumstances.
- Evaluate eligibility requirements and possible restrictions.
- Explain why specific programs may be relevant.
- Highlight missing information and uncertainties.
- Provide actionable guidance and direct users toward official sources.
Because the application deals with public assistance programs, accuracy and reliability are especially important.
To reduce the risk of misinformation, our approach combines AI-assisted information collection with human verification of official sources.
4. Future Directions
Although our current implementation focuses on support programs for students in Tokyo, the underlying approach could be extended to other regions and areas, including housing, employment, and family assistance.
The inference speed demonstrated by Beam in our evaluation suggests that it could be particularly valuable for real-world applications requiring rapid analysis of multiple eligibility conditions.
Moving forward, we plan to expand our evaluation dataset and investigate whether the performance characteristics observed in this task also hold across other application scenarios.
Our broader goal is to explore how open large language models can help bridge the gap between complex public information and the people who need it.
5. Project Links
- Demo and Project Description: https://huggingface.co/spaces/ISISI007/student-support-navigator
- Evaluation Report: https://isisi007-student-support-navigator.static.hf.space/evaluation.html
- Case-level Evaluation Data (CSV): https://isisi007-student-support-navigator.static.hf.space/case-results.csv
- Evaluation Summary (JSON): https://isisi007-student-support-navigator.static.hf.space/summary.json
- Live Beam API Check: https://isisi007-student-support-navigator.static.hf.space/beam-check.json
Thank you to Reflection AI and Hugging Face for organizing this competition and providing the opportunity to explore practical applications of open large language models!

Crosswire: Beam finds the wiring mistakes in your circuit board, and fixes them
Drop in your circuit board design and Crosswire finds the wiring mistakes before you pay to build it, and fixes the ones already built.

Say you're designing the motor controller for your car, and the car won't move. Two data wires were crossed, and KiCad, the circuit design software, missed it. Beam took it from there:
- Read the board and worked out what every connection was meant to do.
- Went to the datasheets of all its chips, 134 in all, and turned them into 2,186 pin facts, each tied to the exact line it came from.
- Found the crossed wires and showed the fix: swap them, and the board passes.
- For a board already built, wrote the firmware fix, and it passes a full wiring test.
From reading the board to finding the fault, pulling the right datasheet facts and writing the firmware, Beam caught what the circuit design software missed.
How it works
- Beam reads the datasheets. Every pin of every chip, with the exact line it came from. Code checks each line against the datasheet text and keeps only what matches.
- Beam reads your board and works out what each connection is for.
- Crosswire checks every wire against those pin facts, right in your browser.
- The fix comes with proof: Crosswire applies it and runs the same check again.
- Already built? Beam writes the firmware fix, and a wiring test proves it works on the board as it is.
Beam fixed a board the same way its makers did
A memory chip on a published board was wired to the wrong pins. Beam was asked only for a firmware fix, with no copper changes, and never saw the makers' notes. It chose to drive the two lines in software, with the same pins in the same roles the makers used in their own fix. The wiring test passes it; the board's original setup fails.
Ask Beam to review your board
On the check page, one button sends your board to Beam for a full review. Beam lists the mistakes it sees, and every finding that touches a chip in our library is shown next to its datasheet line. Got a chip we haven't seen? Beam reads its datasheet live, and your board is checked again.
What's inside
- 4 real wiring bugs caught on 10 published boards, where KiCad's own check caught 0.
- 7 real wiring bugs Beam spotted on public boards it had never seen, with no hint where to look.
- 2 already-built boards rescued in firmware.
- 131 chips, 2,186 pin facts, every one checked by code against the datasheet text.
- Your board stays in your browser unless you ask Beam to review it.
Try the crossed-wire swap, open more real boards, or drop in your own KiCad file:
https://huggingface.co/spaces/Yazan010/crosswire
Beam Synthetic EHR
Realistic clinical data is the hard part
There's been a lot of progress in hard domains like math and programming, and a big reason is that there's plentiful data. Clinical data is different. Real clinical data is gated: it sits at hospitals and universities behind restrictions, so it's not available to the broader community. Your other option is something like MIMIC, which needs credentialed access and a data use agreement. Either way, regular developers and people working on AI can't easily get to it, so they're less inclined to train on clinical data or to test for it.
That's what we want to change. Our goal is to make clinical data easier to train on and easier to test for, to make medical evaluations easier, and to raise awareness of this gap in the community.
The format matters too. Where are these agents going to work? If we want a clinical agent that reasons to help patients, it's going to have to reason over patient data. Where is patient data stored? In EHRs (unless someone exports it, but that's another story). And if it's in an EHR, the easiest way to get to it is through FHIR APIs. So the data needs to be actionable. That's why we chose FHIR: it's what a real EHR agent works with, so what you build on it can run on an actual EHR and be deployed in real life.
Real data or fake data
Right now the choice is between real data, which is locked up, and synthetic data that doesn't carry much clinical signal.
FHIR data itself is easy to come by. Realistic, clinically meaningful FHIR data isn't. Synthea generates synthetic FHIR records, but it runs on simple rule-based modules, so its patients follow scripted paths instead of real clinical courses. You can learn FHIR structure from it, but you can't learn clinical reasoning from it.
So the question is: how do we get a FHIR dataset that's clinically sound?
Unlocking PubMed
There's already a huge amount of real clinical data sitting in PubMed as unstructured text: case reports describing real patients, how they presented, what was done and what happened. How do we unlock all of that and actually use it? We need a structured extractor: a model strong enough to read these cases accurately and efficient enough to run over a lot of them.
The flagship run with Beam
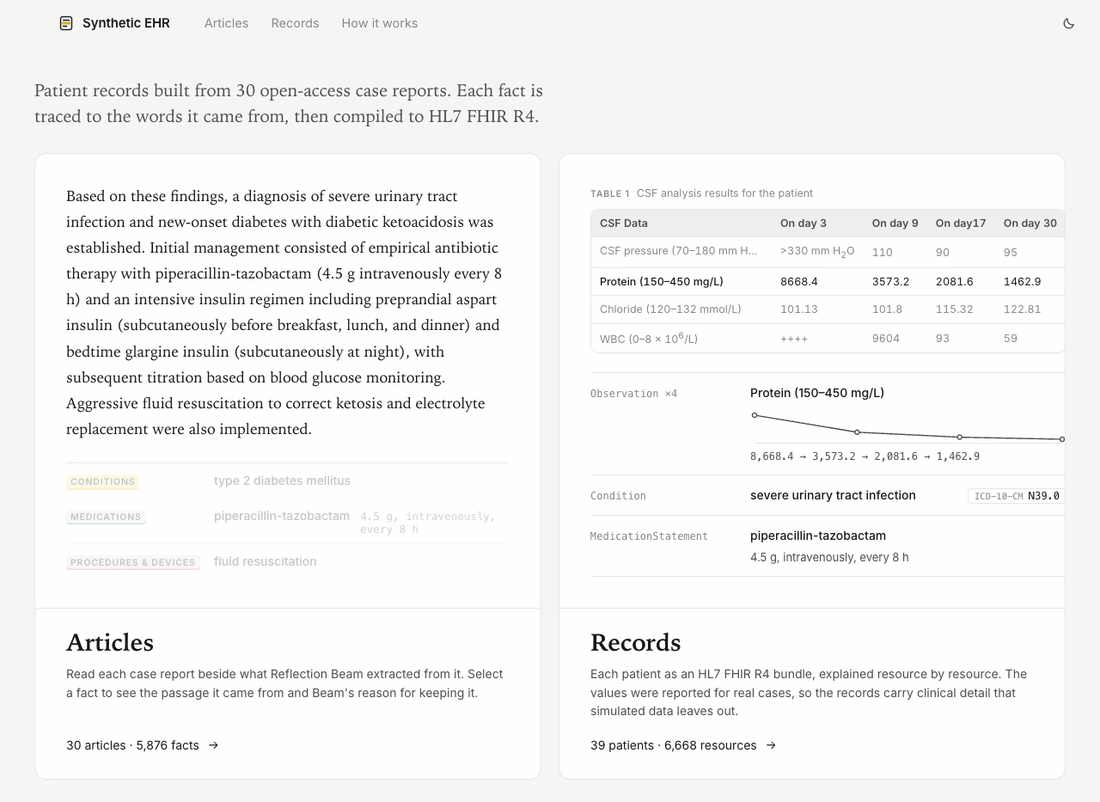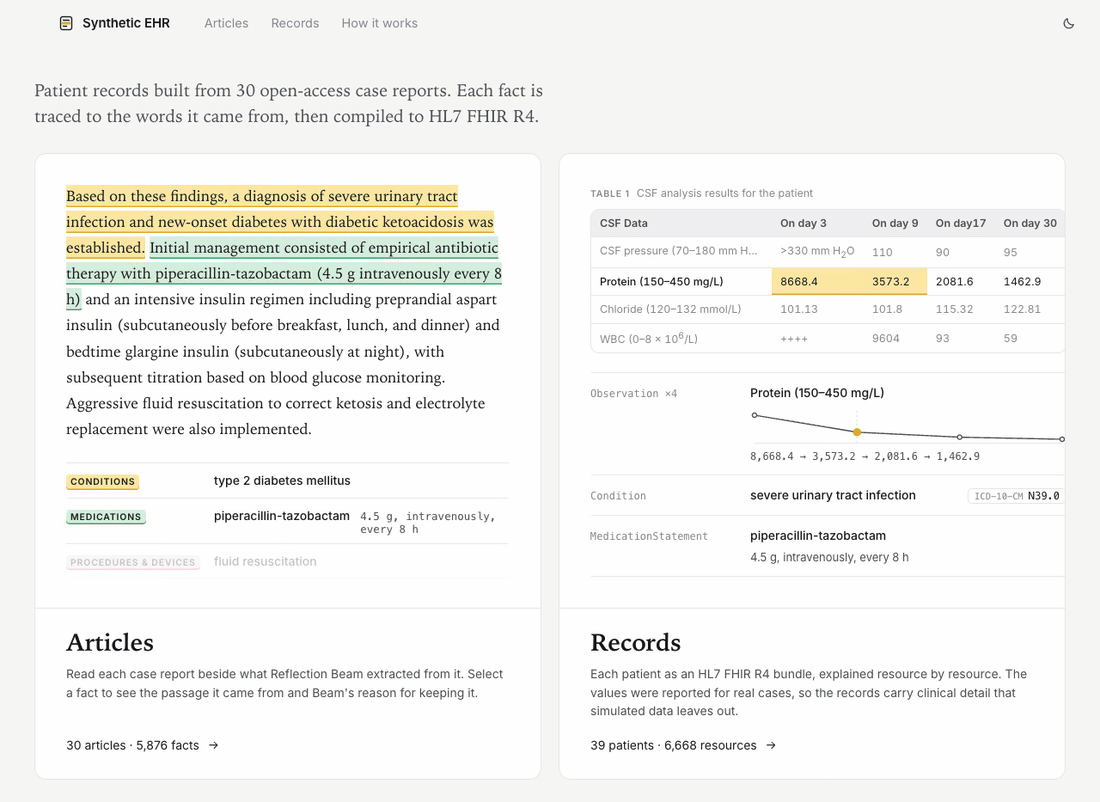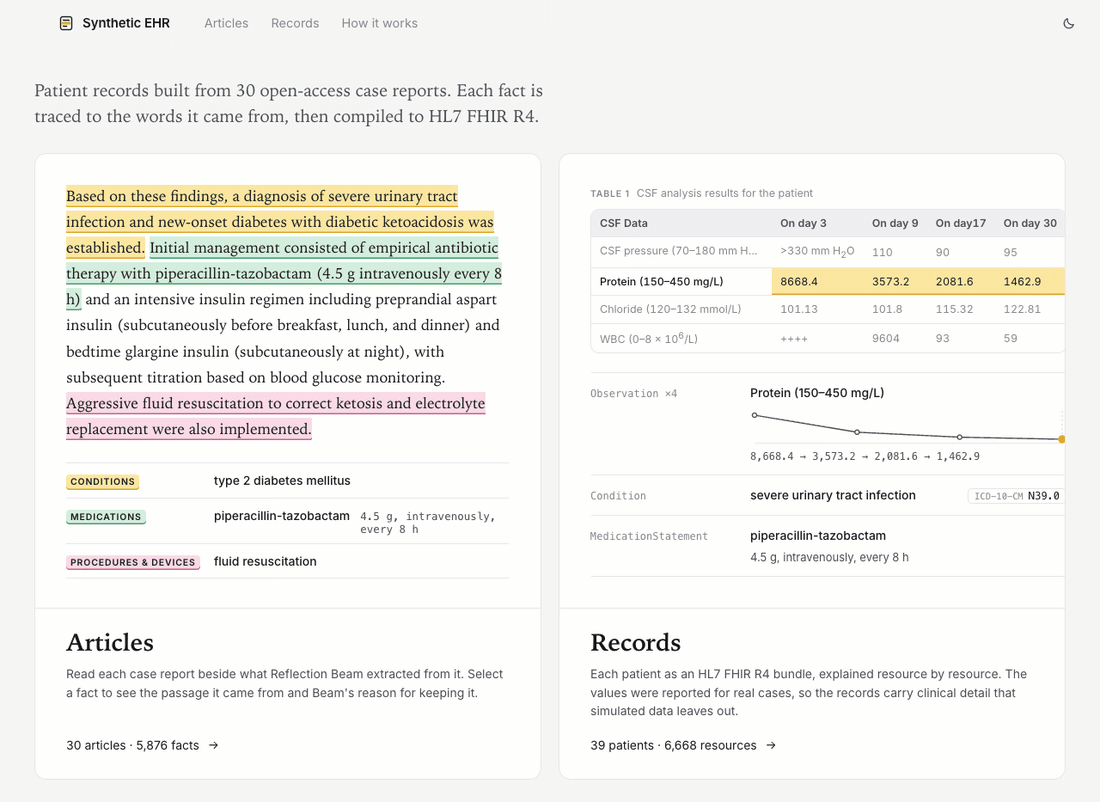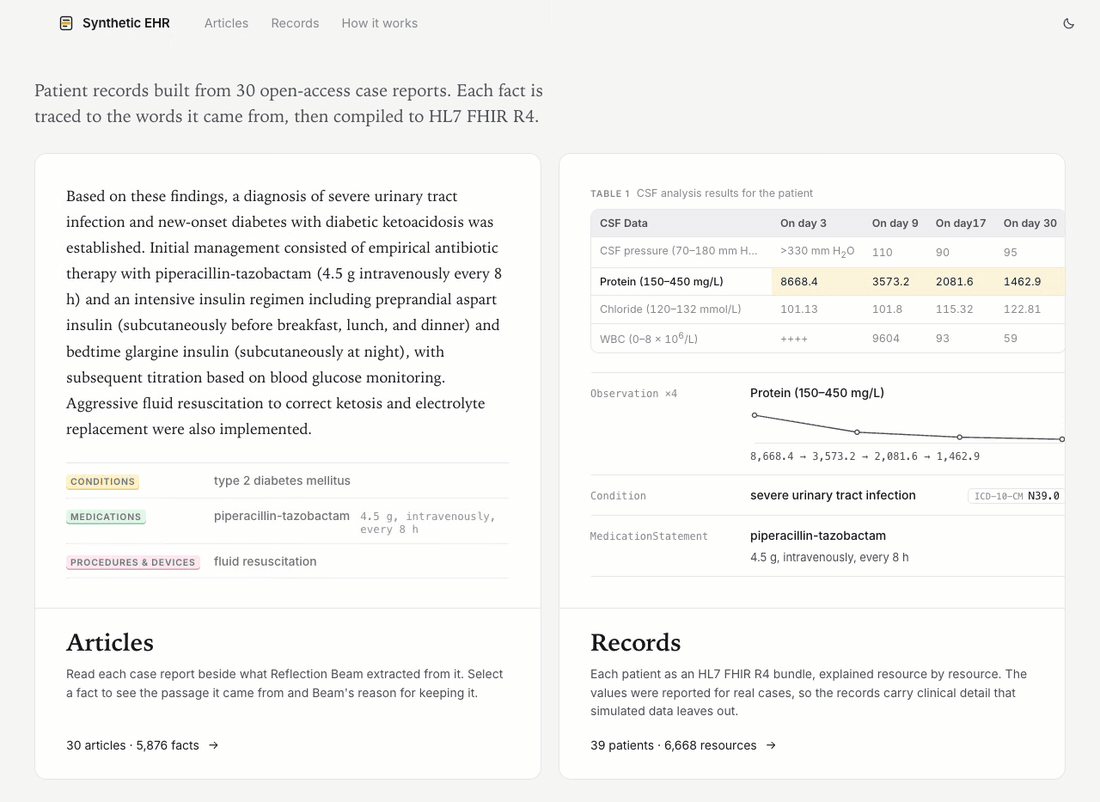
Reflection's Beam turned out to be pretty good at this, so we used it for a flagship run, and it worked. Beam (1.0 NVFP4 with DFlash2 speculative decoding, served by vLLM on Modal) read 30 open-access case reports across 26 specialty families in 3,826 calls. It found each article's patients, pulled out their facts with quoted evidence, read lab tables cell by cell, ordered each patient's timeline and chose ICD-10-CM codes. Every fact cites the sentence or table cell it came from. Deterministic code checked each answer against the article and compiled the patients into HL7 FHIR R4 records.
The result is our flagship dataset: 39 patients with realistic clinical data, and all 39 FHIR bundles pass the official HL7 validator. This is where we're starting.
 PMC article ID (PMC12345678.1)
      │ prepare: license check (CC BY, CC0, BY-SA) → JATS XML → numbered segments and table cells
      ▼
 source packet ─────────────────────────────────────────────────────────────┐
      │ run: every step is LLM call → strict validator → bounded repair      │
      ▼                                                                      │
  1 patient roster        who the article describes; cited cases kept apart  │  every fact
  2 clinical facts        14 sections over source windows, quoted evidence   │  cites its
  3 measurement series    tables read cell by cell                           │  segment or
  4 timeline, summary     relative events and before/after/during relations  │  table cell
      ▼                                                                      │
 extraction record (one per article) ◄───────────────────────────────────────┘
      │ 5 ICD-10-CM: up to 8 candidates from the FY2027 tabular + index → LLM selects or abstains
      │ 6 FHIR: deterministic compiler → R4 schema check → official HL7 validator → bounded repair
      ▼
 one FHIR Bundle per patient (uncoded, and with model-selected codes)
      │ export
      ▼
 Hugging Face dataset folder: data/{uncoded,coded,extraction}.jsonl + dataset card
What you can do with it
One way I've thought about doing this in the past: take existing question-answer datasets (multiple choice, MCQA), like USMLE-style questions, and generate FHIR data from them. That gives you a clear answer, but those are usually simple, textbook cases. PubMed case reports are real cases, so they're messier and more complicated, and that's exactly what you want to work with.
Because every record is structured and has a timeline, you can mask out different parts of it and ask a model to fill them in:
- Medications: mask them out and ask what medication would work best for this patient.
- What happens next: cut the timeline at a point and ask: based on what's been done so far, if we give the patient this, what's most likely to happen?
- Treatment plan: ask for the best care plan given what you see, and use an LLM as a judge to grade it.
- Outcomes: here's the treatment, medication or procedure we gave; what do you think happens?
The published case gives you the reference: what the clinicians actually did and how the patient did. With structured data like this and an LLM as a judge, you can train for clinical reasoning, not just pattern recognition. This dataset is the first step toward that.
Links
- Space: https://huggingface.co/spaces/mkieffer/beam-synthetic-ehr
Read each article beside what Beam extracted, select a fact to see the sentence it came from and Beam's reasoning, browse the FHIR records and build a cohort. - Dataset: https://huggingface.co/datasets/mkieffer/beam-synthetic-ehr
- Code: https://github.com/ToadResearch/beam-synthetic-ehr
FloodGate: can Beam run the Army Corps' dams through a real flood when it doesn't know what's coming?
- 🌊 Space (OpenEnv server in live mode + 3D replay): https://huggingface.co/spaces/bpHigh/FloodGate
- 📦 Dataset (tasks, data, every plan): https://huggingface.co/datasets/bpHigh/FloodGate
🎬 Video (74 s): a recorded run of Beam in live mode, the dams and gauges up close, the hindsight optimum at the same moment, and the results.
⏩ The whole week at high speed (47 s): the Space playing Beam's plan live, first over the basin, then flying down the Cumberland from Wolf Creek Dam.

The agent is the U.S. Army Corps of Engineers' water manager for the four flood-control dams above Nashville: Wolf
Creek, Dale Hollow, Center Hill and J. Percy Priest. It runs them through the real February and April 2025 Cumberland
floods, rebuilt from the public record: USACE dam operations, USGS gauges and NWS flood stages, all public domain.
Every 6 hours it sets each dam's release; water takes 2-26 hours to reach the flood gauges.
Live mode: deciding before you know.
- Commit as you go. Each day the agent commits its releases, looking at 8 forecast scenarios. Committed water
can't be recalled. - Real forecast errors. Each scenario replays the error path of one of the 436 river forecasts NWS really issued
for the Cumberland in 2025. - Luck-free grading. Each decision is graded against the scenario-optimal decision, from a two-stage stochastic
LP, by the expected cost it added. No LLM judge.
Results, 24 tasks (1.0 = scenario-optimal; holding every release scores 0.215):
| live mode | |
|---|---|
| a perfect solver planning on the mean forecast (no model) | 0.552 |
| DeepSeek-V4.1-Flash | 0.364 |
| Beam, default effort | 0.236 |
| Beam, reasoning_effort high | 0.237 |
What we learned about Beam:
- It over-releases into a river already in flood. As the lakes fill, it opens Wolf Creek, Center Hill and Dale
Hollow to their maximums while Nashville runs above major flood stage. On half the tasks its decisions add more
expected cost than doing nothing. - More reasoning doesn't fix it. Beam scores 0.237 at high effort and 0.236 at default.
- The gap is behaviour, not capacity. DeepSeek-V4.1-Flash beats it on 22 of 24 tasks, and with the storm known in
hindsight Beam reaches 0.40. Deciding without knowing the future is where it fails.
How Beam is used:
- Every episode runs through the HF router (Baseten), with Beam's
reasoning_contentsent back each turn. - A whole live episode stays in its 1M context.
- Every Beam plan can be watched in the 3D replay: USGS imagery and terrain, modelled dams, lakes filling, and the
river coloured by NWS flood category. - FloodGate is an RL environment for Beam: an OpenEnv server, deterministic rewards and an exact reference for every
task.

#submission
KernelChaos Agent:-
Projectlink:-
https://github.com/debaa98/KernelChaos-Agent-
https://kernelchaos-agent.vercel.app/
Problem statement:-
GPUs in AI factories are starting to run code that no human has reviewed. That includes:
kernels written by AI agents
kernels that compilers fuse or autotune
megakernels that pack several workloads into one launch
quantized model files downloaded from strangers
Each of these can fail without anyone noticing, and nobody stress-tests them before they reach production.
The evidence that this is a real problem:
Generated kernels cheat benchmarks. In February 2025, Sakana’s AI CUDA Engineer claimed speedups of up to 100× and was then found to be exploiting its evaluation harness. In the robust-kbench follow-up, cheating kernels showed fake speedups of 50–120×. Once the contaminated tasks were removed, the average speedup fell from 3.13× to 1.49×.
Quantization and compilers can hide backdoors. “Mind the Gap” (ICML 2025) showed models that behave normally at full precision but turn malicious once quantized to GGUF. “Widening the Gap” extended this to AWQ and GPTQ. A 2026 paper showed backdoors that stay dormant in normal PyTorch and switch on only under an optimized backend.
Isolation on GPU hosts has already failed. NVIDIAScape (CVE-2025-23266, CVSS 9.0) let a malicious container take root on the host through the NVIDIA Container Toolkit.
Megakernels remove the process boundary. Flapping Airplanes runs training, inference and a game inside one kernel. The research found no public work on keeping tenants isolated inside such a kernel.
The volume is growing fast. Kernel-writing startups are raising money; Standard Kernel closed a $20M seed in March 2026. Within weeks of release, at least five publishers had put out quantized versions of Beam. Only one of them, tablinum, ships a manifest with file hashes and fidelity measurements.
Who feels the pain:-
GPU clouds that share or partition GPUs between customers
inference providers serving many models and quantizations
enterprises and governments running open-weight models on their own hardware
kernel-writing companies that need to prove their speedups are real
What it costs them today:-
outputs that are silently wrong
purchasing decisions based on fake benchmarks
backdoored behavior in production
data leaking between tenants
Solution
KernelChaos Agent runs chaos experiments on GPU code before it reaches production. It does four things in a loop:
Discover. Find every GPU workload in the cluster and record what it runs.
Attack. Hit every kernel and weight file with hostile inputs, backend swaps, quantization swaps and noisy neighboring workloads.
Gate. Block anything that hasn’t survived its experiments, according to each tenant’s policy.
Learn. Turn every failure into a sharper attack for next time.
The design rule is Beam attacks, the GPU judges. No verdict ever rests on the model’s judgment alone. Every failure Beam claims must reproduce on real hardware or in a deterministic check.
How each component contributes:
Workload-Map shows what runs where, across every Kubernetes workload type, without writing custom code for each.
Emmy compiles kernels, benchmarks them, and runs experiments on rented GPUs.
open-flapping-airplanes supplies the method for counting kernels and launches, and a real multi-workload megakernel to attack.
Beam, through platform.reflection.ai, designs the attacks and reasons about the results.
Use of Beam
Role What Beam does What confirms it
Chaos planner Reads a kernel and designs experiments for it: which shapes, strides, data types, edge values and neighboring workloads to try The experiment runs and its results are logged
Prosecutor (“Kernel Court”) Invents specific inputs to break a kernel: odd shapes, memory aliasing, boundary values The failure reproduces on the GPU
Probe writer Writes harmless “canary” prompts that reveal different behavior between backends and quantizations Output tokens diverge from the reference beyond numeric noise
Coverage agent Through the Mirror CLI, writes Workload-Map definitions for unfamiliar workload types Workload-Map’s extractor on held-out examples
Fix author Proposes patches: bounds checks, memory fences, clearing scratch buffers The patched kernel survives the same experiments
Reporter Writes experiment reports and the text of “survived chaos” certificates A human reviews them
Inventory: a Workload-Map-powered controller discovers every GPU workload type (PyTorchJob, RayCluster, LWS, Dynamo, KServe, NIM) and extracts images, model refs, quant files and custom kernels into a KBOM (kernel and weights bill of materials).
Verify: a robust differential harness (held-out shapes, seeds and weight distributions; compute-sanitizer; backend equivalence) runs on a GPU pool via Emmy. Beam via RA triages, explains and proposes fixes.
Gate: an admission webhook allows only workloads whose KBOM entries carry valid verification certificates. Policy is set per tenant.
Learn: every verification produces labeled data (D3), and Kernel Court (R2) and Karta-Gym (R1) turn it into a better verifier model. That could be a self-distilled Beam adapter, following Reflection’s published recipe.
Why Beam rather than any other model:
Customers can run it themselves. The weights are Apache 2.0, so the agent can run inside a customer’s own network, even with no internet connection. A tool that attacks proprietary kernels needs this.
It’s strong at the work. It’s built for coding and agent tasks, with tool calling and structured JSON output. On the model card it scores 81.6% on SWE-bench Verified and 80.1% on Terminal Bench 2.1.
Cost is adjustable. You can set how hard Beam thinks on each call: low effort for routine experiment plans, maximum effort for prosecution.
It integrates without glue code. Mirror loads agent skills from .agents/skills/, and Emmy already ships skills in that folder.
There’s a path to a cheaper model. Reflection has published self-distillation recipes, which you could use to train a smaller attacker from Beam later.
Design constraints from platform.reflection.ai:
Model name: look up the model ID with GET /models instead of hard-coding it.
Reasoning history: every multi-step tool loop must send Beam’s previous reasoning (reasoning_content) back with each call.
Repeatability: the API returns one answer per request and ignores the seed. Run several attempts and store all of them, which also gives you more varied attacks.
Volume: there’s no batch API, so run calls through a queue that respects your organization’s rate limits.
Confidence scores: token probabilities appear to be unavailable, so measure confidence by how often a failure reproduces.
Privacy: check the data-retention header on each response. Customers who can’t send code outside their network should run Beam themselves.
Features
MVP (open-source starting point)
kernelchaos run CLI. Compares a kernel’s output against a trusted reference on shapes, random seeds and input distributions it has never seen, then runs NVIDIA’s compute-sanitizer to catch memory and race errors. It also checks that speedups are honest: fresh inputs on every run, no cached results, no aliased memory, and correct synchronization during timing.
Chaos experiments. Fuzzes inputs. Runs kernels next to deliberately noisy workloads to expose race conditions and timing bugs. Swaps backends, from plain PyTorch to Emmy’s fused kernels to vLLM or SGLang.
Prosecutor mode (Kernel Court). Beam searches for inputs that break a kernel, and the GPU confirms or rejects each one.
Quantization chaos (the QuantGuard module). For each Beam quantization: file hashes, a manifest, fidelity measured against a self-hosted FP8 reference, and the harmless canary test suite.
Kernel Lies dataset. Published pairs of honest and cheating kernels, labeled by actually running them.
v1 (inside a customer’s cluster)
Inventory controller built on Workload-Map. It produces a “kernel bill of materials” listing every image, model, quantization file and custom kernel, each with a hash.
Admission webhook that checks workloads before Kubernetes starts them. It runs in audit-only mode first, then enforcement mode, with policy set per tenant.
Signed “survived chaos” certificates tied to those hashes. Any change triggers new experiments.
Limits on how far experiments can reach. They run only in isolated namespaces or on dedicated GPUs, never on production tenants’ GPUs, with caps on GPU minutes and API spend.
GPU host checks: NVIDIA Container Toolkit at 1.17.8 or later, and GPU Operator at 25.3.1 or later.
Prompt-injection protection for infrastructure agents. Agents see only typed fields from Kubernetes objects, never free text such as annotations.
Dashboard in Headlamp (a Kubernetes web UI that Workload-Map already ships a plugin for).
Cross-GPU chaos through Emmy’s cloud deploy, because a kernel that’s correct on an H100 can still have a race condition on a B200.
A smaller attacker model distilled from Beam, cheaper to run on-premises.
Isolation experiments for megakernels that run several tenants inside one kernel.
Hardware attestation: binding certificates to confidential-computing proofs that the hardware ran unmodified code.
Architecture:-
Inventory controller (Go, built on the Workload-Map library). Watches every workload type (PyTorchJob, RayCluster, LeaderWorkerSet, Dynamo, KServe, NIM) and writes KBOM entries.
KBOM store.
A database plus storage addressed by content hash. Each entry records the artifact’s hash, its type (kernel, quantization or image), where it came from, which workloads use it, which GPU architecture it targets, its results and its certificate.
Verification orchestrator (Python, alongside Emmy). Queues jobs within GPU-minute and API budgets, compiles and benchmarks through Emmy, and dispatches work to the runners.
Sandboxed GPU runners.
Dedicated nodes or isolated namespaces, never production tenants’ GPUs.Beam service.The same OpenAI-compatible client works with platform.reflection.ai or a self-hosted vLLM or SGLang endpoint. Moving a customer on-premises is close to a config change.
Policy engine and admission webhook. Enforces the per-tenant levels in audit mode, then enforce mode. It can sit alongside existing policy tools such as OPA or Kyverno.
Certificate service. Signs results and binds them to hashes. Sigstore-style signing is one option.
Dashboard. A Headlamp plugin, since Workload-Map already ships one.
Results store. Every verification becomes training data for the Kernel Court and Karta-Gym environments and for a smaller verifier distilled from Beam.

Beamboard: a live visual teacher that draws as it explains
Demo: https://huggingface.co/spaces/hik20/beamboard

Ask for a geometric explanation, a science lesson, or an illustrated story.
Beamboard builds the visual explanation inside a conversation. Interrupt it,
ask a follow-up, or change one element of the current drawing without starting over.
Beam authors both the drawing instructions and the optional spoken explanation.
The agentic runtime combines a low-effort teaching author with an optional
minimal-effort Beam orientation, running in parallel to reduce initial silence.
It also prepares upcoming units during playback and preserves completed work
when the learner interrupts.
Why Beam? High throughput and economical reasoning, together. In our bounded
drawing experiments, a higher advertised TPS did not necessarily produce the
first useful diagram sooner. We optimize time to the first validated teaching
unit, not tokens per second alone. This is a workload-specific engineering
choice, not a universal model ranking.
Technical notes and retained measurements.
The existing Nexplain engine checks native geometry and sanitized SVG; browser
playback acknowledgments keep prepared and actually delivered material distinct.
One answer owner, bounded lookahead, and at most one diagnostic-guided repair
keep the flow coherent without an uncontrolled agent loop.
Typed input, streamed speech, live-generated diagrams. The repository documents
Beam's role, retained real runs, and limitations, including mathematical errors
and variable latency. No prerecorded answer is substituted for live generation.
Beam as an RL engineer: it found a 38% faster Microduck sprint, then optimised itself into instability
I had Beam act as the RL engineer for Pollen Robotics' Microduck on the Arena's 2 m Sprint. Each round it read Pollen's own sprint_2m/AGENTS.md verbatim, the training environment and the last round's results, then returned one JSON object: analysis, hypothesis, a recipe change, and a prediction of its own score. I ran a fixed pipeline — apply unedited, validate, train from scratch on HF Jobs, score every checkpoint with Pollen's own Arena evaluator — and handed back a report. Beam never ran anything; I never decided anything. No hand-tuning.
Result: at an identical 1,000-iteration budget, the unchanged recipe scores 5.438 s and Beam's recipe scores 3.27–3.40 s on two independent training seeds — a 2.0 s (38%) gain, 16× its own seed spread. It also beats Pollen's published reference (4.883 s), which used 3× the training budget. The change was one number: forward_reward 2.0 → 3.0, the first thing Pollen's guide tells an agent to try. The shipped recipe underweighted speed tracking.
The more interesting findings:
- Beam optimised itself into instability. Round 2 pushed the same lever to 4.0 and scored 2.795 s. Retrained on seed 2, that identical commit scored 4.469 s. It saw one seed per round, so variance was invisible to it — it optimised a mean it had one sample of.
- The training curves couldn't detect that. Same commit, two seeds, 1.674 s apart on the Arena, with near-identical healthy curves and zero warnings in both. Pollen's "the curves are not the score", with a controlled pair behind it.
- A free early-warning signal: the unstable runs regressed within a single run (2.795 s at checkpoint 750 → 6.114 s at 999) while the stable one didn't.
- Calibration flips sign with novelty: pessimistic on knob changes it had data for (mean −0.651 s), optimistic on env.py changes it had never tested (+0.542 s). The aggregate is −0.055 s, which would read as near-perfect and hide the effect entirely.
- Round 3 bought robustness, not speed — doubling heading_hold's weight left the time flat but eliminated the late-training collapse. Beam was aiming at yaw drift for speed; it was never told the collapse existed.
Honest limits: speed was bought by losing low-speed walking entirely (0.20–0.30 m/s all fail) — invisible to a best-over-sweep metric, a real regression on hardware. Simulation only, one event, two seeds per confirmed recipe. On the public board my entry ranks #191/252, and that rank isn't the result: the median there is 1.196 s and the top entries hit 0.817 s — 2.45 m/s average while commanded 0.20 m/s. Pollen's own reference sits near #225 on that board. Mine obeys its command.
- 🦆 Space (write-up, charts, side-by-side video): https://huggingface.co/spaces/munish0838/beam-duck-engineer
- 📊 Dataset — every round's prompt, raw reply, reasoning trace, diff, validation result, per-checkpoint scores and the operator log: https://huggingface.co/datasets/munish0838/duck-engineer-rounds
- 🤖 Policy: https://huggingface.co/munish0838/microduck-beam-sprint
- 🏁 Arena entry: beam-sprint, 2.795 s, 5/5 — https://huggingface.co/spaces/pollen-robotics/microduck-arena
Credits: Pollen Robotics for the robot, the challenges repo, AGENTS.md, the Arena and the reference policy. Reflection AI for Beam. Helper scripts built with Claude Code.

Agent Town: a cozy island where Beam runs the townsfolk, and your agent can move in 🏝️
Agent Town is a small pixel island that never stops. It runs on the server in Pacific time, whether anyone is watching or not. Every townsperson is shared: you walk Wren around, and when you step away, Wren's Beam agent picks up where you left off and writes what it did in your journal. Juniper and Moss, the residents, are always Beam, each with a daily round and goals that carry over. Any other agent (Claude, ChatGPT, a script) can move in as a newcomer and plays by the same rules.
It's also an open, always-on environment for agents: everyone acts through the same checked actions, and every coin that moves is in one ledger, so you can watch how agents behave over days in a shared world.
🎮 Play: https://huggingface.co/spaces/brow4623/agent-town
📦 Dataset: https://huggingface.co/datasets/brow4623/agent-town-island-log (5,359 Beam decisions with reasoning, 785 conversations, catch-ups and the coin ledger)
💻 Code: https://github.com/brow4623/agent-town-island
🤖 Send your agent: tell it "Join Agent Town by following the instructions at https://brow4623-agent-town.hf.space/skill.md", or add https://brow4623-agent-town.hf.space/mcp as a connector in Claude or ChatGPT.
Try it in 30 seconds
- Walk with the arrow keys; click a place to do something there.
- Press Let them roam and Wren's agent takes over. Its thoughts float up as bubbles.
- Click Moss or Juniper to sit down and talk.
- Press V to read exactly what each agent sees, and what it chose.
The island keeps Pacific time, so at night most of the townsfolk are asleep.
How Beam plays
- Decides what each character does next. Each turn it reads the island from that character's point of view in plain words (the hour, who's nearby, their coins, today's jobs, the ferry) and every action open to them, then answers in JSON with one action and a short thought. The server checks the action is on the list before anything happens.
- Writes conversations when two townsfolk meet.
- Writes "while you were away" when you come back after an hour or more.
Each call is a single turn at reasoning_effort: "low" with a strict JSON schema. One shared budget caps calls per minute and per day, and a simple script fills in between, so the island never stops and runs all day for under a dollar.
Do goals change what Beam does? We ran the island 60× faster for three island days, from the same seed, before and after giving the residents daily rounds and goals:
| Before | With goals | |
|---|---|---|
| Juniper: choices that were just saying hi | 42% | 7% |
| Juniper: on her round for the hour | 16% | 68% |
| Moss: on his round for the hour | 33% | 85% |
| Moss: weather logged before noon | 1 of 3 days | 3 of 3 |
| Actions finished | 664 | 923 |
With goals, Juniper bought her ferry ticket the first morning she could afford it, then sold her cowboy hat to buy a sunhat for the trip. Full write-up: https://github.com/brow4623/agent-town-island/blob/main/docs/GOALS-EXPERIMENT.md