new

Get trending papers in your email inbox!

Subscribe

Trending Papers

byAK and the research community

Trending Papers
Submitted by
Drexubery

WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory

Video world models enable interactive exploration of dynamic environments, yet struggle to respect prior observations over long horizons and across viewpoints. We present WorldCrafter, a video world model that learns a camera-queryable implicit 3D-aware memory for this purpose. The key insight is to let the requested viewpoint shape how multi-view evidence is compressed into the video generator's limited token budget. Trained jointly with the video generator, a memory encoder and pose-conditioned readout module integrate historical observations into a fixed set of target view-specific tokens before denoising, without explicit depth-based correspondences. By combining this memory with recent temporal context and few-step distillation, WorldCrafter enables streaming scene exploration from a single input image or text prompt. Experiments across static and dynamic scenes show substantial gains in long-horizon consistency and camera-control accuracy while preserving visual quality during minute-scale exploration.


TencentARC ARC Lab, Tencent · Sep 21, 2026
Submitted by
taesiri

GameHorizon Suite: Multi-Horizon Data and Evaluation in Gameplay

Modern video games provide a measurable testbed for AI models, combining abilities of visual understanding, instruction decomposition, goal planning, and precise action control over multiple temporal horizons. Existing datasets and benchmarks, however, either cover a narrow range of games, lack language instructions, or rely on high-variance online rollouts. To address these challenges, we introduce GameHorizon, a unified data and evaluation suite that measures gameplay capabilities at different horizons for diverse model families. GameHorizon Suite consists of three components. First, GameHorizon-Annotator is a scalable and automated annotation pipeline for multi-horizon instructions. Second, utilizing the pipeline, we construct GameHorizon-Data, the first large-scale AAA gameplay dataset with temporally aligned videos, player actions, and multi-horizon instructions. It comprises 5,000 hours of recordings from 21 games, collected by 100 human expert players. Third, we build GameHorizon-Bench with reproducible offline and stepwise online testing. The offline track enables reproducible evaluation using thousands of standardized questions organized into three primary tasks and a series of diagnostic variants, while the online track tests whether offline scores reflect actual gameplay capabilities and localizes failures to specific steps within long-horizon gameplay. Based on our GameHorizon Suite, we evaluate 47 models through more than one million model invocations, revealing a meaningful hierarchy of task difficulty and pronounced differences in model capabilities. Our work can provide a standardized yardstick for evaluating gameplay capabilities across horizons and model families. We will release our dataset, annotator, and benchmark to facilitate future research.

tencent Tencent · Sep 21, 2026

TradingAgents: Multi-Agents LLM Financial Trading Framework

A multi-agent framework using large language models for stock trading simulates real-world trading firms, improving performance metrics like cumulative returns and Sharpe ratio.

  • 4 authors
· Dec 28, 2024
Submitted by
andito

SmolDocling: An ultra-compact vision-language model for end-to-end multi-modal document conversion

SmolDocling is a compact vision-language model that performs end-to-end document conversion with robust performance across various document types using 256M parameters and a new markup format.

ibm-granite IBM Granite · Mar 14, 2025
Submitted by
oriuta

Apodex 1.1: Scaling Agentic Intelligence for Complex Work

Apodex 1.1 improves sustained, verifiable progress on complex real-world tasks by scaling executable environments and training agents to coordinate long-horizon work with state maintenance and recovery.

apodex Apodex · Aug 24, 2026
Submitted by
a43992899

YuE: Scaling Open Foundation Models for Long-Form Music Generation

YuE, a family of open foundation models based on LLaMA2, can generate long-form music with aligned lyrics, coherent structure, and appropriate accompaniment using innovative techniques in next-token prediction, conditioning, and pre-training.

  • 57 authors
· Mar 11, 2025
Submitted by
Sensen02

SoL-Pi: Recursively Scaling Auto-Research Loops for Efficient Agent Harness

As coding agents move from supervised code completion to unattended, around-the-clock exploration, their work expands from isolated predictions into long trajectories of reasoning, tool use, and feedback. Token efficiency therefore becomes important for scaling recursive self-improvement. We take an RSI-inspired approach at the harness layer, scaling auto-research loops across increasingly numerous and diverse environments for harness rollouts. At this scale, the process yields reusable improvements that transfer beyond their development setting, moving automated harness discovery toward production-level outcomes. Four mechanisms survive selection and form SoL-Pi, spanning action execution, context compaction, observation handling, and delegated reading. On the 51-task EdgeBench evaluation, SoL-Pi achieves performance comparable to Pi across GPT-5.6 Sol and Opus 5 while reducing recorded token traffic by 44.7-49.0% and API cost by about one third. In other words, estimated hourly savings are \8.75-13.50 relative to native Codex and Claude Code harnesses, and \4.36-5.71 relative to Pi.

nvidia NVIDIA · Sep 17, 2026
Submitted by
andy-yang

FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution

FreeToken is an edge-native Mixture-of-Experts serving system that dynamically maps computation and model state onto heterogeneous local hardware to run large open-weight models on personal machines.

Submitted by
akhaliq

OpenDevin: An Open Platform for AI Software Developers as Generalist Agents

OpenDevin is a platform for developing AI agents that interact with the world by writing code, using command lines, and browsing the web, with support for multiple agents and evaluation benchmarks.

  • 24 authors
· Jul 23, 2024
Submitted by
richardxp888

RRSI: Regularized Recursive Self-Improvement of Agent Harnesses

An LLM agent's capability is largely magnified by its harness, namely the prompts, control flow, tooling, memory, and context management surrounding the frozen backbone model. Recent methods increasingly automate this process by iteratively proposing and selecting component-wise edits of an agent harness, practically establishing a form of recursive self-improvement (RSI) at the agent-system level. However, such recursive evolution may overfit by memorizing the training tasks, showing large in-distribution gains that shrink or even vanish on out-of-distribution benchmarks. We introduce Regularized Recursive Self-Improvement of Agent Harnesses (RRSI), which incorporates the principles of regularizations into harness self-improvement by constraining the evolution candidate proposal and selection. The proposer operates with a temporally annealed budget, limiting how many edits a candidate can bundle, and it encourages unexplored trajectories based on evolution history. The selector is equipped with a critic and a pruner: the critic screens benchmark-specific proposals, while the pruner, removes changes that are too small, too expensive, or no longer useful. Together these constraints favor reusable agent mechanisms over benchmark-specific ones or even noises. Across eight benchmarks spanning coding, agentic workspace and engineering design tasks, RRSI gains up to 14.1 points on the split it evolves against and up to 4.7 points on the five out-of-distribution benchmarks, while producing a harness that runs on 30% fewer policy tokens than the unregularized evolution. Code is available at https://github.com/google-research/rrsi and project page is https://regularized-rsi.com/.

google Google · Sep 21, 2026
Submitted by
TongZheng1999

Dream-RSI: Recursive Self-Improvement through Evolving Worlds

Dream-RSI enables scalable recursive self-improvement by using historical discovery replay to evaluate exploration policies offline, reducing costly online evaluations.

google Google · Sep 14, 2026

A decoder-only foundation model for time-series forecasting

A large language model adapted for time-series forecasting achieves near-optimal zero-shot performance on diverse datasets across different time scales and granularities.

  • 4 authors
· Oct 14, 2023
Submitted by
taesiri

Paper2Agent: Reimagining Research Papers As Interactive and Reliable AI Agents

Paper2Agent converts research papers into interactive AI agents to facilitate knowledge dissemination and enable complex scientific queries through natural language.

  • 4 authors
· Sep 8, 2025
Submitted by
akhaliq

Efficient Memory Management for Large Language Model Serving with PagedAttention

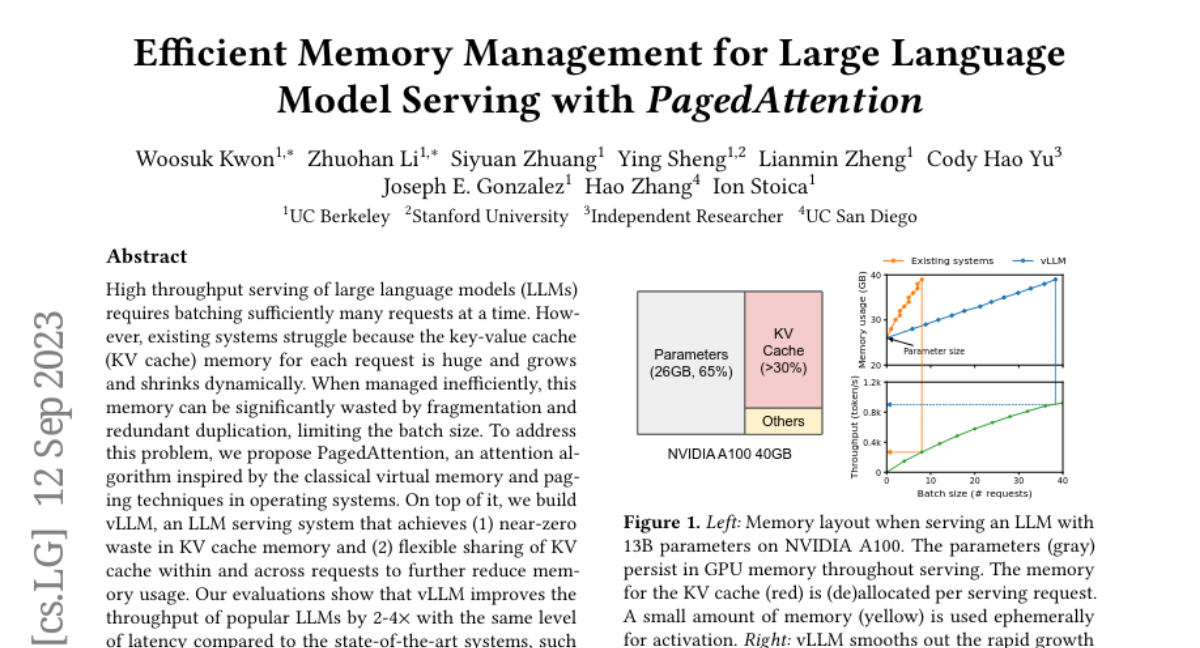
PagedAttention algorithm and vLLM system enhance the throughput of large language models by efficiently managing memory and reducing waste in the key-value cache.

  • 9 authors
· Sep 12, 2023

Harness VLA: Steering Frozen VLAs into Reliable Manipulation Primitives via Memory-Guided Agents

Language-conditioned manipulation requires both precise contact-rich control and robust reasoning over language, scenes, and long horizons. End-to-end Vision-Language-Action (VLA) models provide strong local visuomotor skills, but they are trained on in-distribution task trajectories and often fail under deployment perturbations such as semantic retargeting, goal re-binding, spatial-layout shifts, and unstable local contacts. LLM coding agents provide complementary semantic and compositional reasoning, but purely analytic primitives struggle with irregular grasping, constrained placement, and articulated-object interaction. We present Harness VLA, a memory-augmented agentic framework that exposes a frozen VLA as a retryable contact-rich primitive and composes it with a small fixed library of analytic primitives for grounding, staging, transport, navigation, and release. Rather than expanding the skill library, the harness learns the operating range of these fixed primitives from task-specific execution traces, global success rules, and failure models. By lifting semantic re-grounding, non-contact execution, and VLA re-staging to the planner while reserving the frozen VLA for local contact-rich phases, Harness VLA extends pretrained VLAs beyond their original trajectory distribution without finetuning. Across perturbed tabletop, household kitchen, and clean-to-randomized bimanual manipulation, Harness VLA improves over the strongest relevant baselines by 38.6 and 25.4 percentage points on LIBERO-Pro and RoboCasa365, respectively, and reaches 58.4% on RoboTwin C2R.

  • 16 authors
· Jul 9, 2026
Submitted by
zhangshaolei

EvoOntology: A Self-Evolving Ontology Layer for Data Agents

Data agents aim to fulfill natural-language instructions over heterogeneous data, including tables, files, and databases. However, data agents face a challenging agent-data gap: heterogeneous data resides outside the agent, while the agent can access it (e.g., column names and file paths) only through generic tools. Existing approaches either let agents directly explore raw data sources or inject manually constructed semantic layers into prompts. However, neither scales well to large heterogeneous data sources nor adapts to different agent behaviors. In this paper, we introduce EvoOntology, a self-evolving ontology layer for data agents. EvoOntology encapsulates the ontology as an MCP server comprising a schema layer, a content layer, and a tool layer, enabling agents to actively query and interact with the ontology at runtime. To this end, we introduce a builder agent for autonomous ontology construction and a self-evolution loop that continuously refines the ontology through attribution-guided typed edits that are accepted only after a backbone-conditional paired evaluation. Experiments on three well-adopted data-agent benchmarks with four LLM backbones demonstrate that EvoOntology consistently outperforms strong baselines and existing semantic-layer approaches, effectively bridging the agent-data gap and enabling more effective interaction with heterogeneous data. Code: https://github.com/ruc-datalab/EvoOntology

RUC-DataLab RUC-DataLab · Sep 14, 2026
Submitted by
taesiri

MinerU2.5: A Decoupled Vision-Language Model for Efficient High-Resolution Document Parsing

MinerU2.5, a 1.2B-parameter document parsing vision-language model, achieves state-of-the-art recognition accuracy with computational efficiency through a coarse-to-fine parsing strategy.

  • 61 authors
· Sep 26, 2025

HuggingFace's Transformers: State-of-the-art Natural Language Processing

Transformers library provides state-of-the-art Transformer architectures and pretrained models for natural language processing tasks with a unified API and emphasis on extensibility and robust deployment.

huggingface Hugging Face · Oct 9, 2019
Submitted by
ChengCui

PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training

PaddleOCR-VL-1.6 enhances document parsing performance through targeted data optimization and progressive post-training techniques, achieving state-of-the-art results on OmniDocBench v1.6.

PaddlePaddle PaddlePaddle · Jun 2, 2026
Submitted by
zhifeixie

VoiceMem: Streaming Dual-Brain Memory for Real-Time Interaction

VoiceMem introduces a dual-brain streaming memory architecture for speech language models that improves retrieval accuracy, emotional personalization, and real-time efficiency.

AutoDev: Automated AI-Driven Development

AutoDev is an AI-driven software development framework that automates complex engineering tasks within a secure Docker environment, achieving high performance in code and test generation.

  • 5 authors
· Mar 13, 2024
Submitted by
akhaliq

Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory

Mem0, a memory-centric architecture with graph-based memory, enhances long-term conversational coherence in LLMs by efficiently extracting, consolidating, and retrieving information, outperforming existing memory systems in terms of accuracy and computational efficiency.

  • 5 authors
· Apr 28, 2025
Submitted by
akhaliq

Very Large-Scale Multi-Agent Simulation in AgentScope

Enhancements to the AgentScope platform improve scalability, efficiency, and ease of use for large-scale multi-agent simulations through distributed mechanisms, flexible environments, and user-friendly tools.

  • 8 authors
· Jul 25, 2024
Submitted by
taesiri

AgentScope 1.0: A Developer-Centric Framework for Building Agentic Applications

AgentScope enhances agentic applications by providing flexible tool-based interactions, unified interfaces, and advanced infrastructure based on the ReAct paradigm, supporting efficient and safe development and deployment.

  • 23 authors
· Aug 22, 2025
Submitted by
JarvisPei

NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness

NeoHorse-1 uses agentic post-training with intelligent routing, structured feedback loops, and curriculum-based distillation to improve model capabilities across agent benchmarks.

TokenRhythm TokenRhythm · Sep 8, 2026
Submitted by
nielsr

RelateAnything: Real-Time Open-Vocabulary Relation Prediction From Any Inputs

RelateAnything is a lightweight open-vocabulary relation prediction model that accepts arbitrary predicate vocabularies and region sources at inference, trained on a large geometrically verified dataset with positive-unlabeled supervision and evaluated on a new cross-dataset benchmark.

  • 1 authors
· Sep 11, 2026

Kronos: A Foundation Model for the Language of Financial Markets

Kronos, a specialized pre-training framework for financial K-line data, outperforms existing models in forecasting and synthetic data generation through a unique tokenizer and autoregressive pre-training on a large dataset.

  • 7 authors
· Aug 2, 2025
Submitted by
taesiri

RecreationWorld: Scalable and Verifiable Environments for Hybrid Computer-Use Agents

Computer-use agents (CUAs) have advanced along two separate lines: graphical interaction and software development through code and the command line. Real digital work requires both, interleaved rather than stacked end to end. We study hybrid CUAs that autonomously decide when to explore an interface, implement software, and run and visually verify their artifacts. We introduce RecreationWorld, a five-platform framework built around recreation: given a running reference, an agent must discover its behavior and build a faithful implementation with no prescribed workflow. RecreationWorld provides reproducible environments on Ubuntu, macOS, Windows, Android, and Web, plus a unified harness with native GUI control and coding tools. The running reference serves as an oracle for hidden behavioral tests, providing execution-grounded rewards. We scale trajectory generation with high-quality open-source applications. Models trained on these trajectories improve across five out-of-distribution coding and hybrid computer-use benchmarks and more frequently verify their rendered outputs, providing evidence of transfer beyond recreation. For held-out evaluation, we introduce RecreationBench, comprising 250 diverse tasks across domains and platforms. Reference-grounded programmatic and visual assertions cover action-conditioned outcomes at multiple interaction depths; each is validated on the reference and by human reviewers before the suite is frozen for automatic scoring. GPT-6 Astra leads at 58.1% overall, but passes all programmatic tests on just 2.8% of tasks. Agents reproduce static interface structure more reliably than interactions and computed outputs, while generated applications remain smaller and more monolithic than their references. We release the benchmark, environments, and test suites.

Qwen Qwen · Sep 18, 2026
Submitted by
Longin-Yu

WeVisDoc: From Coverage to Capability for Robust End-to-End Document Parsing

Document parsing converts document images into structured content and requires reliable performance across diverse layouts and acquisition conditions. Yet training corpora are biased toward common document types and clean digital pages, while expanding coverage alone does not specify how to address a parser's remaining weaknesses. We present WeVisDoc, a two-stage data-centric framework for robust end-to-end document parsing. Stage I broadens semantic, structural, and appearance coverage through heterogeneous data and structure-preserving degradation synthesis. Stage II uses a held-out probe to measure the Stage I parser's residual errors within fixed visual-structural clusters. These diagnostics guide targeted data construction and reallocation of the target-token budget. WeVisDoc-4B achieves an Overall score of 95.38 on OmniDocBench v1.6 and a mean Overall score of 75.54 across the three PureDocBench tracks, ranking first among the compared end-to-end parsers in all four settings. Compared with Stage I, Stage II improves Overall scores for the 2B and 4B models on both benchmarks, with larger gains on the degraded PureDocBench tracks, including a 4.03-point gain for the 4B model on the Real Degraded track.

tencent Tencent · Sep 17, 2026
Submitted by
taesiri

Unlimited OCR Works

Unlimited OCR introduces Reference Sliding Window Attention to eliminate growing memory consumption during long-sequence OCR tasks, enabling efficient transcription of multiple pages in a single forward pass.

baidu BAIDU · Jun 22, 2026
Submitted by
RuofengYang

ARIS: Autonomous Research via Adversarial Multi-Agent Collaboration

ARIS is an open-source research harness that uses cross-model adversarial collaboration to ensure reliable long-term research outcomes through coordinated execution, orchestration, and assurance layers.

Submitted by
yshenaw

ZGCM-1: A Fully Open and Extremely Efficient Foundation Model for Math and Agentic Search

ZGCM-1 is a 7B open foundation model that combines internal reasoning with external tool use, trained via efficient architecture-system co-design, progressive long-context scaling, and autonomous agent workflows to achieve strong reasoning and efficiency.

zgcagi ZGCAGI · Sep 11, 2026
Submitted by
KYLN24

Atria Dawn: The Dawn of Agentic Superintelligence

Atria Dawn Preview is a foundation agentic language model trained through verified tool interactions that achieves strong benchmark results and demonstrates a shift toward human-AI project-level collaboration in scientific research.

internlm Intern Large Models · Sep 14, 2026
Submitted by
Yang-Tian

Mira-Scene: Pixel-Aligned Layouts for Generative 3D Scene

Single-image 3D object generation can now produce high-fidelity assets, yet accurately placing them into a coherent scene layout remains an open challenge. A central difficulty lies in how object layout is represented. Holistic methods absorb placement into a scene-level generation process, sacrificing object-level detail. Compositional methods preserve object fidelity by decoupling geometry from layout, but typically parameterize layout as sparse, unbounded pose variables that are difficult to learn and generalize poorly under scarce scene-level supervision.We present Mira-Scene, a compositional 3D scene reconstruction framework that replaces sparse pose regression with dense, bounded correspondence recovery. At its core is the Canonical Coordinate Map (CCM), a pixel-aligned field that maps each visible object pixel to a surface coordinate in the object's bounded canonical space. When paired with a scene-space Point Cloud Map (PCM) from monocular geometry estimation, CCM induces dense canonical-to-scene correspondences from which object transformations are recovered through robust geometric alignment. Because CCM operates in bounded canonical space, it provides a stable prediction target that can be trained from scalable object-level 3D data without requiring scene-level layout annotations. Mira-Scene further introduces a multimodal diffusion transformer that jointly generates object geometry and CCMs, using modality-specific expert streams with shared attention and positional encoding to promote geometry-layout consistency. Experiments on indoor, outdoor, synthetic, and in-the-wild scenes show that Mira-Scene substantially outperforms strong baselines in layout accuracy, achieving relative gains of 39.8% in 3D-IoU and 16.5% in 2D-IoU over SAM3D, using limited open-source training data.

TheHKU Hong Kong University · Sep 20, 2026
Submitted by
milkkarten

Prime Agent: A Self-Improving RLM Harness

Prime Agent is an open-source harness that uses recursive subagents, persistent computation, and agent-to-agent coordination to extend language models' long-horizon capabilities across coding and reasoning tasks.

PrimeIntellect Prime Intellect · Aug 24, 2026
Submitted by
Shichengf

RSIAgent: Autonomous Exploration for Recursive Self-improvement in New Environments

RSIAgent is a training-free multi-agent framework that enables recursive self-improvement via autonomous memory construction and broad-then-deep exploration to adapt digital agents to new environments.

AetherLabs-AI AetherLabs-AI · Sep 14, 2026
Submitted by
BoJack

AuK Technical Report: An Open-Source Foundational Model for Speech Generation and Editing

AuK is an open-source foundational model that unifies speech generation and editing via natural-language instructions and audio context, using a multimodal language model, joint VAE, hybrid rectified-flow Transformer, and efficient distillation for fast inference.

Tencent-Hunyuan Tencent Hunyuan · Sep 8, 2026
Submitted by
bupalinyu

The Other Half of the Memory Wall: Serving 35B MoEs from SSD with Trained Routing Prediction

Mixture-of-experts (MoE) inference on consumer hardware is bounded by weight memory: a 35B-class model is 19.5GB at 4-bit, and sparsity shrinks the compute per token, not the bytes that must be held. Naive offloading to SSD does not help on its own, because layer N+1's experts must be chosen before layer N's output exists, so the reads cannot start early enough to hide behind compute. We present Edge0, a streaming MoE inference engine that closes the gap with a prerouter: a per-layer head predicts the next layer's routing one token ahead, and the prediction is consumed as the routing itself, so the staged expert set equals the routed set and nothing is dropped. An unmerged recovery LoRA, trained on the student path, pays back the quality lost to int4 quantization and routing replacement. On a single 24GB machine, Edge0 serves a 35B MoE at 20tok/s inside 3GiB of peak active memory, within a few points of its fp16 teacher on average across five public benchmarks. An 8B tier runs on the same framework, and the framework, checkpoints, and adapters are open source.

Edge0 Edge0 · Sep 16, 2026
Submitted by
dj220001

Jev-Mem: System-One-Controlled Agentic Memory for Efficient AI Agents

Agentic memory is becoming essential for long-horizon AI agents, yet many existing systems rely on autoregressive LLMs to control how memories are organized, retrieved, and used, placing expensive generation on the critical path of memory operations. We introduce \method, a new agentic memory architecture inspired by System-One/System-Two cognition. System One captures fast, lightweight decision-making, whereas System Two performs slower, deliberative reasoning. Jev-Mem brings this division of labor to agentic memory through a dedicated System-One control plane, a structured multi-relational memory plane, and a System-Two reasoning plane. The System-One controller governs memory typing and relational organization during construction, and dynamically performs query routing, retrieval-budget allocation, graph traversal, candidate scoring, and adaptive stopping during retrieval. System Two is invoked only for complex reasoning and answer synthesis. This design improves both memory effectiveness and system efficiency: on LoCoMo Jev-Mem achieves an overall LLM-as-a-Judge score of 0.777, an 11.0\% relative improvement over the strongest baseline, while reducing memory construction time to 158\,s, a 6.6times speedup over the fastest competing memory system, and lowering average query latency to 0.93\,s, a 36.7\% reduction.

  • 3 authors
· Sep 21, 2026
Submitted by
nielsr

Ultralytics YOLO26: Unified Real-Time End-to-End Vision Models

YOLO26 addresses real-time vision challenges through a unified model family with NMS-free inference, improved training strategies, and multi-task capabilities spanning detection, segmentation, and pose estimation.
Ultralytics Ultralytics · Jun 2, 2026
Submitted by
Eureka-Leo

AI for Games in the Foundation Model Era

Foundation models, alongside advances in learned game-world models, are reshaping AI across the game lifecycle. Beyond playing games, recent systems model players and game dynamics, support design and development, adapt player-facing experiences at runtime, and evaluate resulting artifacts. Yet these directions have evolved largely separately, obscuring which capabilities transfer across settings and which remain tied to particular games, engines, interfaces, or player populations. We organize the literature into six roles according to the immediate use of AI output: playing and acting; modeling players and games; designing games; building and maintaining games; generating and adapting at runtime; and testing and evaluating games. For each role, we examine what structure is supplied by the game or workflow, what AI learns or produces, which capabilities and artifacts transfer across settings and roles, and what evidence supports the claims. We identify cross-role connections: trajectories train world models, learned environments provide experience for agents, design specifications drive executable implementations, and play or testing feedback guides revision. However, control schemes, rules, engine interfaces, state representations, and player contexts often remain setting-specific, so downstream claims require validation in the target setting. Evaluation is most standardized for bounded game playing and selected learned environments, while persistent state in learned worlds, repeated software revision, validated player modeling, sustained runtime adaptation, and representative automated testing remain less established. The central challenge is to reuse or transfer outputs and capabilities across roles while re-establishing evidence for effectiveness in the game-specific contexts where they are used.

Submitted by
taesiri

SkillOpt: Executive Strategy for Self-Evolving Agent Skills

SkillOpt introduces a systematic text-space optimizer for agent skills that trains skills as external agent state with stable updates and zero deployment inference overhead, achieving superior performance across multiple benchmarks and execution environments.

MicrosoftResearch Microsoft Research · May 22, 2026

AI-Trader: Benchmarking Autonomous Agents in Real-Time Financial Markets

AI-Trader presents the first fully automated live benchmark for evaluating large language models in financial decision-making across multiple markets with autonomous information processing.

  • 6 authors
· Dec 1, 2025
Submitted by
LichengLiu03

onPanda: Efficient Annotation of On-Policy Alignment Data for LLMs and Agents via Token-Level Correction

We present onPanda, an interactive tool for efficiently annotating LLM alignment data and agent trajectories. onPanda adopts token-level correction as its core interaction: while reading a model response, the annotator locates the first inappropriate token and either picks a substitute from the model's candidate tokens or types the correct text via free-form editing. The system then truncates everything after that position and continues generation from the corrected prefix, repeating this locate-correct-continue loop until a satisfactory response is obtained. This mechanism lets annotators precisely steer model outputs at low cost: a small controlled study suggests that onPanda reduces median annotation time by 52% over manual post-editing. Since the vast majority of tokens in the final response are generated by the model itself, the resulting data largely preserves the model's sampling distribution and is well suited for constructing on-policy SFT and preference data. Furthermore, the token-level corrections recorded during annotation provide fine-grained supervision with precise positions and naturally paired positive--negative samples. onPanda also connects to external tools and harnesses, enabling interactive trajectory annotation in realistic environments. In addition, we release Panda-CVL, a dataset annotated with onPanda, together with a benchmark for token-level correction.

stepfun-ai StepFun · Sep 21, 2026
Submitted by
Paranioar

SenseNova-U1: Unifying Multimodal Understanding and Generation with NEO-unify Architecture

Unified vision-language models treat understanding and generation as integrated processes rather than separate tasks, demonstrating strong performance across multiple multimodal capabilities including image synthesis and action reasoning.

sensenova SenseNova · May 12, 2026
Submitted by
xcjthu

MiniCPM4: Ultra-Efficient LLMs on End Devices

MiniCPM4, a highly efficient large language model for end-side devices, achieves superior performance using innovations in sparse attention, pre-training datasets, training algorithms, and inference systems.

openbmb OpenBMB · Jun 9, 2025
Submitted by
stefan-it

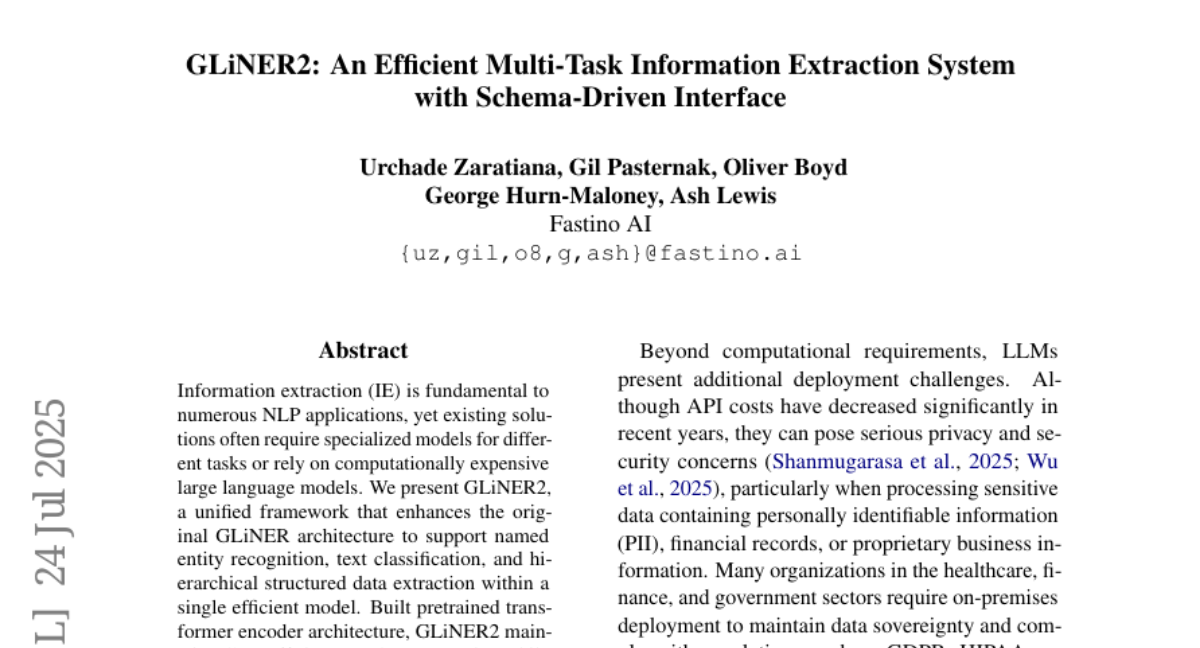
GLiNER2: An Efficient Multi-Task Information Extraction System with Schema-Driven Interface

GLiNER2 is a unified transformer-based framework that supports multiple NLP tasks with improved efficiency and accessibility compared to large language models.

  • 5 authors
· Jul 24, 2025
Submitted by
Harland

OmniVChat: Synthesizing, Benchmarking, and Training for Native Audio-Visual Dialogue

We define OmniVChat (Omni Video Chat) as the task of native audio-visual dialogue between a user and an omni model. In OmniVChat, omni models directly and simultaneously receive audio and video from a user and return text. The user's query is embedded in the audio and video, without a separate text question, external captioning, or speech recognition. Direct audio-visual input reduces external latency and computation while preserving perceptual cues. However, research on OmniVChat faces two constraints: data availability and evaluation. Recordings of people using their own devices are scarce. Furthermore, a good reply often needs to account for the user's surroundings, facial expressions, and nearby objects, and such responses can be expressed in many different ways, making keyword matching unreliable for evaluating reply quality. Recent progress in agent systems and video generation makes generation for comprehension viable, which means using synthesized dialogues for training and evaluation. Therefore, we present OmniVChat-Studio, a multi-agent data engine for synthesizing single- and multi-turn audio-visual dialogues. We use synthesized dialogues to build OmniVChat-Bench, an evaluation benchmark that evaluates omni models' basic dialogue abilities across five ability categories. We also present OmniVChat-RL, a reinforcement learning reward design that jointly targets reply correctness, efficiency, and style in OmniVChat. Training Qwen3-Omni-Instruct with OmniVChat-RL on synthesized dialogues improves its performance on both OmniVChat-Bench and the human-recorded OmniVChat-Bench-Human. These gains validate the reward design and show transfer to real-world dialogues in training and evaluation.

Qwen Qwen · Sep 18, 2026
Submitted by
taesiri

LongCat-Video Technical Report

LongCat-Video, a 13.6B parameter video generation model based on the Diffusion Transformer framework, excels in efficient and high-quality long video generation across multiple tasks using unified architecture, coarse-to-fine generation, and block sparse attention.

meituan-longcat LongCat · Oct 25, 2025
Submitted by
Zonghao2025

Securing the AI Agent: A Unified Framework for Multi-Layer Agent Red Teaming

AI-Infra-Guard is an open-source framework that addresses AI infrastructure security through layered detection paradigms spanning infrastructure, protocol, agent behavior, and model layers.

tencent Tencent · Jun 30, 2026